Hacker News

Furifont, a Japanese font that shows furigana

199 points by plaguna ago | 43 comments

TazeTSchnitzel |next [-]

I think this is a rare “useful” abuse of font ligatures, and in that respect I think this is a cool project, but it's also a terrible idea that nobody should actually use, because Japanese kanji readings are famously ambiguous and context-dependent. The modal character has two different readings without counting those used in personal names, nor contextual slight changes to pronunciation. Some characters have six different readings, and that's again without counting those used in personal names. There's no way a font can do a good job at it unless you can somehow stuff an entire LLM in there.

For context, it's a hard enough problem that Google Translate's own romanised pronunciation guides are frequently wrong, or disagree with their text-to-speech.

michaelmior |root |parent |next [-]

> unless you can somehow stuff an entire LLM in there.

Well, it wouldn't be the first time ;)

https://fuglede.github.io/llama.ttf/

Armecera |root |parent |next |previous [-]

Yeah, I already see a few mistakes just looking at this page. But I guess still useful?

silvertab |root |parent |previous [-]

> but it's also a terrible idea that nobody should actually use, because Japanese kanji readings are famously ambiguous and context-dependent

Seems a bit drastic. Don't use it as the main font in a japanese textbook, sure, but use it with the disclaimer that it's not perfect and will get some readings wrong? Why not, still pretty useful. Should people also not use Google Translate? (also, you can stuff an entire llm in a font, it's been done).

Sophira |root |parent [-]

The point of furigana is to be exact - it's a pronunciation guide, and its purpose is to distinguish or to teach. If it's wrong, then nothing makes sense.

If I asked you 'are you a sewer (pronounced "soo-er")?', would that make sense? Maybe if you looked at it hard enough and thought about it, but in the meantime, I would probably get some very strange looks for asking.

shun_dev |next |previous [-]

Really nice font! Native Japanese speaker here, and seeing furigana done purely in the font is very cool.

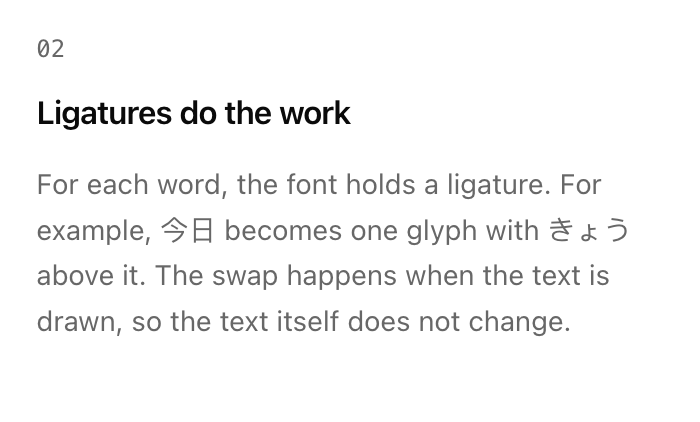
One small thing on the Japanese version of the page: in the "Ligatures do the work" section, 合字 itself only gets じ over 字, and 合 has no reading. It should be ごうじ. I guess 合字 isn't in the dictionary, so it falls back to single kanji, and 合 is skipped because it has several readings.

teshigahara |next |previous [-]

Automatic furigana is not really possible to be reliable considering readings heavily rely on context that can't be easily inferred, but I'm sure it will help some people who can't read very well.

krackers |root |parent [-]

You can run LLMs inside the shaping engine, so maybe you can use more advanced segmenting and transliteration algorithms? https://fuglede.github.io/llama.ttf/

IsTom |root |parent |next [-]

It can depend on implied information, e.g. 方 can be hou or kata depending on if you're talking about about direction or a person. And that information can be before it, after it, on some image next to it, etc.

cubefox |root |parent |previous [-]

"Your scientists were so preoccupied with whether or not they could, that they didn't stop to think if they should."

jwolfe |next |previous [-]

This is very cool. Unfortunate that it gives the wrong pronunciation when words get split in a line wrap (e.g., 大学 got split between lines and changed to incorrect furigana for me).

alasano |next |previous [-]

This is really nice. I'm able to read Hiragana and Katakana fully after about 4-6 weeks now but then I'm hit with the reality of how many Kanji I have to learn still everytime I want to read something in real life lol

orangea |next |previous [-]

I'm seeing Chinese versions of kanji on this website; the HTML might need a language annotation or something. https://i.postimg.cc/NGTvHP4x/Screenshot-2026-10-17-at-12-00...

roughly |next |previous [-]

That’s incredible. I’m always impressed with the utility of the TrueType/open font spec - the flexibility there is really an underappreciated work of engineering genius.

andreareina |root |parent |next [-]

Arguably one of those cases where the capability is awesome, but using the capability is wat.

https://www.destroyallsoftware.com/talks/wat

layer8 |root |parent |previous [-]

I mean, fonts are Turing-complete [0], so it isn’t surprising that this is possible. Turing-completeness is often by accident rather than by genius [1].

[0] https://litherum.blogspot.com/2019/03/addition-font.html

[1] https://en.wikipedia.org/wiki/Turing_completeness#Unintentio...

roughly |root |parent [-]

Which makes sense, because human language is apparently Turing complete, so anything intended to represent it faithfully would wind up with that characteristic, too.

layer8 |root |parent |next [-]

Human language isn’t a formal language, so this is a category error.

In the present context, an example is that the common reading of a Kanji word isn’t always well-defined, and neither is the decomposition of a sequence of Kanji characters into words.

roughly |root |parent [-]

It's often used as one, though.

layer8 |root |parent [-]

roughly |root |parent [-]

It's an interesting move to point me to a rigorously written English language definition of a formal language to make the argument that humans don't co-opt our natural languages as formal languages when the need arises.

layer8 |root |parent [-]

That’s not what “formal language” means. English being used to describe a formal definition doesn’t make it a formal language.

roughly |root |parent [-]

I didn’t say it was a formal language, I said humans co-opt it as one.

anonymous908213 |root |parent |previous [-]

Bitmap fonts aren't turing complete. The fact that TrueType is built with an arbitrary virtual machine is insane, makes implementations ridiculously complex, and is a huge security liability. The purpose of the VM wasn't to "represent human language faithfully" but to make fonts look a little better when displayed at a variety of resolutions, via hinting. Hinting doesn't necessarily require a full VM, but somebody let the engineers have a little too much fun.

roughly |root |parent [-]

And yet, actually mapping all written human languages and their ligatures, variations, etc, seems to require this level of complexity. So the choice is either you draw the line and decide which languages you consider legitimate or not, or you build a machine of sufficient complexity to capture all languages, and the tradeoff, I suppose, is how much knowledge you want to actually be able to capture in your computerized system.

anonymous908213 |root |parent [-]

Unicode is distinct from, and completely unrelated to, TrueType. Unicode does not require a virtual machine to interpret. You can simply express languages and their variations with Unicode + bitmap fonts.

roughly |root |parent [-]

Unless you want ligatures.

anonymous908213 |root |parent [-]

Do you really believe the only way to implement ligatures is with a virtual machine? Dumb and dirty psuedocode written in 5 seconds of thinking about it but come on, this is not that complicated.

  for each character in text
    characterToPrint = Parse(character)
    if character is LigatureStartCandidate
      characterToPrint = LookAheadForNextLigatureCandidateAndResolve(character)
    Print(characterToPrint)

roughly |root |parent [-]

And you've now gotten 92% of the way there. Iterate a few dozen more times to get up to 97%, 98%, 99%, etc., and eventually you'll have rewritten OpenType.

anonymous908213 |root |parent [-]

Would you like to elaborate on those few dozen more cases rather than handwaving them away? Embedding a VM into a font format is foundationally a ridiculous idea and should require real justification, although I know our industry is in love with anything that allows arbitrary code execution exploits.

jbm |next |previous [-]

This is an interesting use of ligatures for sure. However, I really don't know when one would use it. Couldn't you just use Ruby tags for a website?

yorwba |root |parent |next [-]

When you control the content, I agree that ruby tags would be better, since they can easily handle alternative readings and also enable smarter automation to infer the correct reading from context.

But you could set this as the default system font for Japanese and enjoy furigana everywhere, even in places that don't support ruby tags at all.

numpad0 |root |parent |next |previous [-]

Maybe this is less dependent on rendering engine or easier to use. Or maybe because it could be done and was done.

From practicality standpoint, this would not work on unprepared texts, as pronunciation of Japanese words are a bit arbitrary and so correct pronunciations would need to be manually selected for each words.

i.e. "maize" could be read "corn". I believe LLMs don't necessarily have good intuition for that, being trained on plain texts.

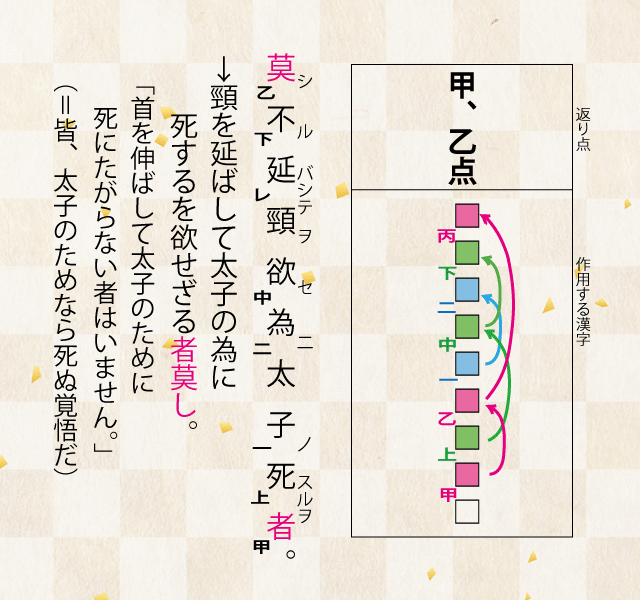
As to how could such a situation could ever manifest: I would blame the fact that the official language of historical Japanese governments having been a really creative interpretation of medieval Chinese[1] sprinkled with labels and jumps and supplements[2][3], resulting in people just accepting wild divergence between literal and spoken Japanese. I'm not a linguist or a language major so I'd happy if anyone could further elaborate...

1: https://en.wikipedia.org/wiki/Kanbun

2: https://youtu.be/_k0I6bi2pYs?t=248

3: https://d1ysbfo9sxjda0.cloudfront.net/wp-content/uploads/201...
guipsp |root |parent |previous [-]

Why do something manually when it can be done automatically?

mminer237 |root |parent [-]

So you can know it's correct and fix mistakes?

luke-fugu |next |previous [-]

This is AWESOME for Japanese learners. There are 46 basic hiragana that represent the sounds of Japanese but many thousands of Kanji, and it’s incredibly hard to read Japanese even if you’ve been studying for years.

A few people here rightly pointing out inaccuracies and other methods of display (ie Ruby tags) but IMO they are somewhat missing the usefulness here - there are many applications (ie e-readers, random web contexts, custom apps etc) where the traditional methods of display are hard or fail. I recently ran into it trying to get custom Japanese ebooks to display furigana with ruby tags on my kindle. It’s a giant nightmare. Excited to try this out.

notorandit |next |previous [-]

> With the ligatures to adopt to pronunciation of words.

Maybe it is:

With the ligatures to adApt to pronunciation of words.

paulsutter |next |previous [-]

I want furigana on display glasses, like Even Realities. Since the application would know my vocabulary, it can show just the words that I'm not likely to know.

Assuming you could hint the furigana from the application, the phonetic transcript would make it more accurate.

croisillon |next |previous [-]

nice, we could do a lithuanian stress font this way too

zerozerotwo |next |previous [-]

This could be really useful as a decoding tool when you don’t know the kanji

peterburkimsher |next |previous [-]

If you want to make romaji, I built Pingtype:

https://pingtype.github.io/japanese.html

It also supports line breaking, so that words don't get cut in half when wrapping text.

igor_nast |next |previous [-]

This is cool!

popalchemist |next |previous [-]

[dead]

ramon156 |previous [-]

> javascript is required ... due to browser limitations

confusing when you don't explain which limktations this is